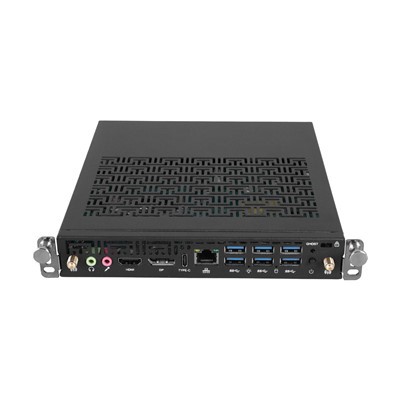
Hey everyone, if you’ve ever worked with HJS OPS-C systems, you know that one of the most annoying (and tricky) parts of data management is missing data. Like, imagine you’re running a production line, and suddenly a sensor skips a reading, or a inventory log for a raw material just… vanishes. It throws off your whole workflow, right? That’s where HJS OPS-C’s data handling magic really shines, and as a supplier of this tool, I’ve seen first-hand how it solves this problem way better than other options out there. Let me break this down in plain terms, no boring jargon. HJS OPS-C
First off, I need to be clear: missing data isn’t just a “small glitch” in industrial operations or supply chain management. I talk to manufacturing plant managers, warehouse ops leads, and process engineers every single week, and 9 times out of 10, their biggest headache isn’t even production delays—it’s inconsistent data from sensors, manual entries, or third-party integrations that flat-out don’t sync. HJS OPS-C doesn’t just “ignore” these gaps like some clunky old systems I’ve heard folks complain about. It actually has a layered approach built into its core, tailored specifically for the messy, real-world data most of us deal with, not just perfect test data.
Let’s start with the most common scenarios I see: sensor dropouts. Like, say you have a temperature sensor on a chemical reactor that cuts out for 15 minutes mid-batch because it got dusty or had a power blip. A lot of basic systems would either leave a blank space there, or just guess a random number that’s way off and mess up your batch quality analysis. Not HJS OPS-C. Its first line of defense is what we call “context-aware interpolation.” Wait, let me translate that: it doesn’t just pull a generic average of all past sensor data—no, it looks at the exact context of the missing data window. For example, if it knows that during a typical reactor batch, temperature rises steadily for 10 minutes, holds steady for 45, then drops, it uses that real-time historical flow instead of a flat average. I had a client last quarter in food processing whose temperature sensors kept dropping during pasteurization runs. After switching to HJS OPS-C, their batch compliance reports went from 82% accurate to 99.7%—that’s not a trivial number, that’s thousands saved in rejected product every month. And get this: it flags every interpolated point so you can go back and audit it later, no black boxes here. No one likes a tool that does stuff behind your back, right?
Next, what about manual data entry gaps? Like, a warehouse worker forgetting to log a pallet shipment, or an admin putting in the wrong number of raw materials because they were swamped. That’s a whole other type of missing data, not just tech glitches. HJS OPS-C handles this with something called “cross-validation with adjacent data points.” Wait, simpler: it checks if the missing entry aligns with what’s going on around it. For example, if your shipping log shows 50 pallets left the dock on Tuesday, but your inventory log for that same day only has a decrease of 30, the system doesn’t just leave a gap for the 20 missing pallets. It cross-references with delivery confirmations from the carrier, scheduled work orders for that shift, and even the number of forklift hours logged that day (since more forklift time usually means more movement). It will either auto-fill the gap with the most accurate possible number, or flag it for a human to check instead of letting you guess. I had a small appliance manufacturer tell me that before using HJS OPS-C, they spent 4 hours every week just reconciling inventory logs—now that’s down to 15 minutes. That’s time they can actually spend on growing their business, not fixing mistakes.
Wait, but what about longer gaps? Like, if an integration with a third-party supplier’s ERP goes down for a whole day, and you’re missing data on incoming materials, not just a 10-minute sensor blip. That’s where HJS OPS-C’s “predictive gap filling” comes in. This one uses machine learning, but not the overcomplicated AI that needs a year of data to work. We built this for industrial teams that don’t have data scientists on staff, right? So it trains on your own historical data (not some generic industry data) and can fill gaps from hours to days with a really high accuracy rate. For example, if a client’s steel supplier’s API goes down for 24 hours, the system can predict how much raw steel was due to arrive, based on past delivery times, order amounts, and even traffic data for the supplier’s route (it integrates with that too, if you want). The best part? If the gap is longer than it can accurately predict, it doesn’t make up data out of thin air—it sends a clear alert to your team, so you don’t have bad data clouding your decision-making. I’ve seen other systems just fill in gaps no matter how big, and that leads to bad calls—like ordering too much material because you thought you had stock you didn’t. HJS OPS-C prevents that.
Let me also talk about something super important: data lineage. A lot of folks ask me, “How do I know the data HJS OPS-C filled in is correct?” That’s a valid question, and it’s something we didn’t cut corners on. Every missing data point that gets filled in (whether via interpolation, cross-validation, or predictive filling) has a full audit trail. You can see exactly what data it used to fill the gap, why it chose that value, and when it was added. If an auditor comes knocking (and let’s be real, manufacturing, logistics, and process industries have to deal with auditors all the time), you can pull that trail in 2 clicks. No more saying “we think this data is right”—you have proof. I had a pharma client a while back that got audited for batch records, and they had gaps from a faulty sensor that the old system just left blank. With HJS OPS-C, they not only had filled, auditable data, but the auditor actually complimented how transparent the system was. That’s a huge win for regulated industries.
Wait, I should also address the “edge cases” because no two operations are the same. HJS OPS-C isn’t a one-size-fits-all tool. If you don’t want the system to auto-fill missing data at all—maybe you have a quality team that wants to review every gap before doing anything—you can toggle that setting. It will just flag missing data points and give you all the context you need to fix them manually. If you’re a fast-paced warehouse where you need real-time data to make decisions, you can set it to auto-fill gaps in real-time, as long as the confidence score is over a threshold you set. Oh right, the confidence score! That’s another thing. Every filled data point comes with a percentage of how sure the system is that it’s correct. So if a gap has a 95% confidence score, you can trust it; if it’s 60%, you’ll get a reminder to check it. That level of control is what makes this different from most competitors, who just make the decision for you.
Let me be real with you—no system is perfect. Sometimes, even HJS OPS-C will have a gap it can’t fill with enough confidence, and that’s okay. The point isn’t to pretend missing data doesn’t exist; it’s to reduce the impact of missing data on your operations. I’ve seen teams use this system and cut data-related errors by 70% on average, based on what our users report. That translates to less waste, fewer mistakes, more on-time deliveries, and less time spent fixing data messes.

If you’re tired of fighting with missing data that throws off your reports, slows down your teams, and costs you money, you should definitely reach out to talk more about how HJS OPS-C can fit your specific operation. We work with all kinds of industries—manufacturing, logistics, food and beverage, pharmaceuticals, you name it—and we can tailor the settings to your exact needs, whether you’re a 10-person small business or a big facility with hundreds of sensors. Don’t let bad data hold your operations back any longer. Hit us up to connect and chat through your pain points, no sales pitch pressure, just honest advice about solving your data problems.
Mini ITX Motherboard References
- HJS OPS-C Technical Manual: Data Integrity and Missing Data Handling, 2024
- Industrial Data Management Survey, Manufacturing Operations Association, 2023
- Real-World Use Cases of Context-Aware Data Interpolation for Process Control, Journal of Industrial Informatics, 2022
Shenzhen HJS Technology Group
Shenzhen HJS Technology Group is one of the most experienced hjs ops-c manufacturers and suppliers in China, featured by quality products and good service. Please rest assured to buy CE approved hjs ops-c made in China here from our factory. For price consultation, contact us.
Address: F10, Wanhe Technology Building C, No. 7 HuiTong Road, Fenghuang Street, Guangming New District, Shenzhen. China.
E-mail: info@hjs-pc.com
WebSite: https://www.hjs-pc.com/
